This is a special post for quick takes by Jesse Hoogland. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
Implications of DeepSeek-R1: Yesterday, DeepSeek released a paper on their o1 alternative, R1. A few implications stood out to me:
- Reasoning is easy. A few weeks ago, I described several hypotheses for how o1 works. R1 suggests the answer might be the simplest possible approach: guess & check. No need for fancy process reward models, no need for MCTS.
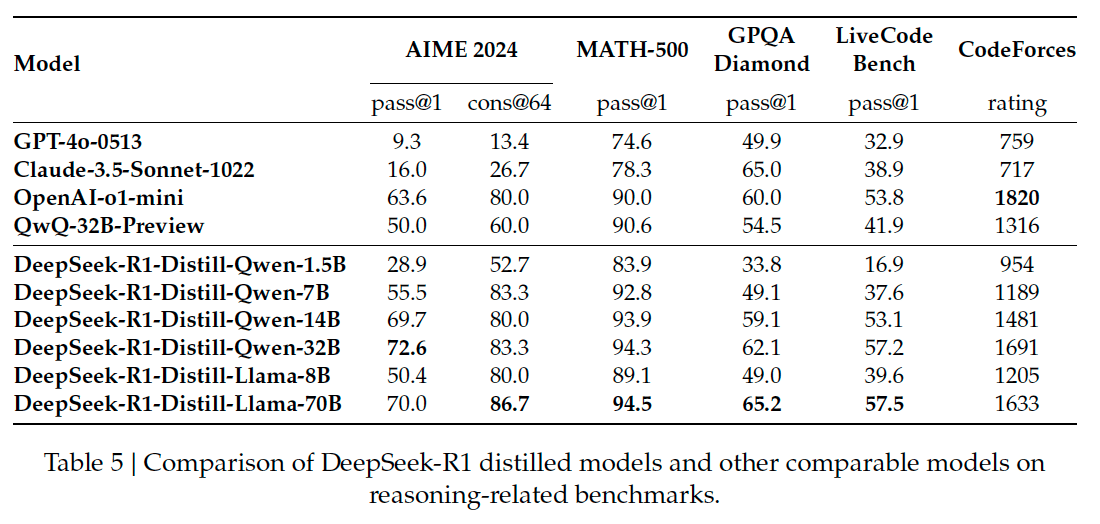
- Small models, big think. A distilled 7B-parameter version of R1 beats GPT-4o and Claude-3.5 Sonnet new on several hard math benchmarks. There appears to be a large parameter overhang.
- Proliferation by default. There's an implicit assumption in many AI safety/governance proposals that AGI development will be naturally constrained to only a few actors because of compute requirements. Instead, we seem to be headed to a world where:
- Advanced capabilities can be squeezed into small, efficient models that can run on commodity hardware.
- Proliferation is not bottlenecked by infrastructure.
- Regulatory control through hardware restriction becomes much less viable.
For now, training still needs industrial compute. But it's looking increasingly like we won't be able to contain what comes after.
 1