I'm worried that people won't reflect well and so (1) they'll decide to use the cosmic endowment for something mediocre and/or (2) they'll have a catastrophic failure in some of {decision theory, bargaining, dealing with threats, reasoning about simulators, acausal trade (including ECL etc.)}. Some angles:
@Wei Dai reacted "examples?" to my
There are other things Wei Dai has talked about and some of them I don't yet grok
so:
I feel like I'm supposed to be anxious from the news about all the AI hacking incidents and the egregious misalignment going on, coupled with them clearly being on-track to become superhuman at math and hacking. But I find that I'm pretty zen about it.
On reflection, I suppose it's due to a confluence of three things:
@Aghyad Deeb @ryan_greenblatt and I just published "Towards understanding score-seeking in LLMs", which I think sheds some light on the general question of whether AIs hack because of score-seeking or proxy drives. I think it will be of interest to you and onlookers.
The physical world is a simple thing that's not useful to study too much, once intelligence scales well past the human level. Almost all cognition is going to be about the computations designed by cognition (or their semantics), not about the physical world, which is likely to be almost entirely relegated to the role of compute substrate for the intentionally designed computations. All of the physical world might one day be about as relevant to most people as the arcane details of material manufacturing processes necessary to make a specialized industrial ... (read more)
Ah, ok. I agree on "unclear" so we disagree less than I thought. I could see an analogous case of: "Maybe in the future, there will be many low-intelligence agents, because there will be some governance system that forces all agents except one to be low-intelligence, for security reasons. We should be extensively studying low-intelligence agents in agent foundations for this reason." And some but not all reasons why this is not a compelling argument for studying low-intelligence agents (in agent foundations) translate to studying "agents with no quantum tech".
I have previously expressed skepticism about modeling time horizons as superexponential (absent feedback loops from AI speeding up AI R&D). In particular, I didn't buy AI Futures Project's argument that there are "meta-skills" that let humans do projects of arbitrary length.
Spelled out in more detail, my skepticism was coming from something like the following argument:
Thanks. Yeah, @Alexander Barry shouldn't the time and money budget given to the AIs scale at the same speed as the time and money budget given to the humans? Tasks that take humans longer, take humans longer, and also cost more to hire humans to do.
I donated to Pause AI UK today.
Why this org in particular?
1) Right now, AI advocacy is clearly the most important thing to do.
2) I've been to some of their protest and one more event, so I know they are doing good work.
I think that donating "close to home" in the sense of point 2, is underrated in EA.
This is why Pause AI (and every other serious AI Safety advocacy group I know about) is advocating for global pause/stop/slowdown.
To be clear, I don't think that "if I don't do it, someone else will" is an acceptable excuse for raising to RSI (shame on all the frontier labs). But everyone pausing together is both an easier sell and a bigger win, and therefore the obviously right thing to advocate for.
Last night I gave a talk at a local social meetup. The topic was very broad ("Economic and social impact of AI in the near future") and I had only 20 minutes, plus Q&A. The audience was about 15 people, mostly business folks. At the start we did a show of hands who's positive or negative about AI, it was about an even split.
My talk itself was very negative about AI, as expected. The slides are here. We ended up having over an hour of discussion after the talk, and people were very interested and receptive.
Around 8 years ago Dario Amodei, Jan Leike and a few others predicted that we’d probably have AGI by now. Since then, AI capabilities have progressed so fast that many people updated that the short timelines advocates were right. And yes, their expectations about the speed of AI progress were far more directionally correct than almost anyone expected. But we don’t in fact have AGI (even under relatively weak definitions, like a reliable drop-in replacement for central examples of white-collar jobs), and the world would look very different if we did.
Now a l... (read more)
good point, this has moved me a bit
When I try to picture the current AI tech stack killing everyone, I still don't really see it. No, not even if it is successfully assembled into an RSI loop that rapidly reaches that tech stack's pinnacle.
I don't think we're in the crunch time.
All things considered, DL still has terrible sample-efficiency and generalization. It needs a ton of data to develop a given capability, much more data than humans, and there's some sense in which what it learns are the "most shallow" capabilities consistent with a given data distribution. Not literal lookup tables, ... (read more)
FWIW it's not super obvious to me that you need "true creativity" (or whatever ??? capability that we think is missing from LLMs) to kill humanity off either; I'd written something along these lines there.
I do think you need a significant amount of crystallized competence[1] in domains like long-term strategy and metacognition/"keeping yourself on-track". Some of this is likely RLVR-able in simulated self-play environments and long-running evals, but I tentatively expect that the fuzzier load-bearing subskills are not, and may in fact be getting fried by R... (read more)
Some basic skepticism regarding Nick Cammarata's recent writeup:
I recently gave talk in the One World Seminar on Combinatorics on Words about stringological sequence prediction, video is available here.
Master post for ideas about infra-Bayesianism.
The anti-Newcomb problem is a puzzle proposed by LessWrong user @drnickbone as a challenge to UDT. I rediscovered it in 2015 and gave it a name. Recently, Richard Ngo mentioned a reminiscent but actually pretty different puzzle called "Newcomb's revenge". All of those are cases in which CDT apparently outperforms FDT.
Of course, one can always construct a decision problem that diagonalizes against any given decision theory. The interesting question is defining a natural class of "fair" problems for which a given decision theory is optimal. One can then argu... (read more)
Thursday night update: OpenAI replies:
A note from our research leaders:
Last week we parted ways with Jasmine, Mikita, and Tomek after a thorough investigation found they violated clear policies on handling sensitive information. Our internal investigation uncovered a significant breach of trust beyond what’s outlined in the letter they published and we stand by the decision to not continue their employment. We generally keep individual employment matters private and don't believe a back and forth would be productive or lead to a resolution, but we want to ... (read more)
May be useful to ask your favorite LLM "From a realist perspective, what do companies do when they want to minimize vs maximize the chilling effect of firing employees?"
Incredibly crude alignment technique. Rot13 all text and training data, except for a small corpus of unusually good data.
Imagine you have a small corpus of data from good ethical people, and a large corpus of data that's full of 4chan trolls or reward hacking or some other bad thing. (The large corpus isn't just trolls, there is useful data in there too)
The hoped for benefit is that the AI displays all the useful knowledge that can be extracted from the large corpus, but only displays the behavior patterns found in the small corpus.
So suppose the 4chan data contains a few useful maths ideas, and also a lot of slurs. And suppose the good data consists entirely of maths proof... (read more)
Another rough alignment idea.
The non-overlap principle. The basic idea, identify the convergent instrumentally useful cognition, and avoid it.
Suppose you ask the AI to cure cancer, and to find a room temperature superconductor. This principle says that there should be 0 overlap between the thought processes used in these 2 ideas. The cancer curing AI should avoid doing any thinking that would be useful in general. Figuring out how to hack it's way out and access the internet is useful in general. Sure, there are things that are generally useful that migh... (read more)
I mean an AI that doesn't write code is safer than one that does. But if you set an AI to cure cancer, you probably don't want it thinking about say Volcanology in too much detail. If the AI doesn't find anything, thinking was a waste of compute. And if the AI does find a means of "curing cancer" that involves the details of volcanoes, I expect it won't be a solution I like. You want to make the AI focus on just biochemistry and nothing else.
I regret each of the thousands of hours I spent on my power-seeking theorems, and sometimes fantasize about retracting one or both papers "Optimal policies tend to seek power." I am pained every time someone cites "Optimal policies tend to seek power", and despair that it is included in the alignment 201 curriculum. I think this work makes readers actively worse at thinking about realistic trained systems.
I think a healthy alignment community would have rebuked me for that line of research, but sadly I only remember about two people objecting that "optimal... (read more)
Updated Oct 7, 2026:
I think, in my despair of the "optimality" mental trap, I went too far with the parent comment. I likely subconsciously exaggerated my feelings to increase rhetorical impact ( :S ). I do not, at this point, regret each of the thousands of hours I spent on the theorems, and probably I didn't fully regret it at the time of writing.
I was recently subpoenaed by the New York City Council. Here is my opening statement, which includes several new facts about why I left Google DeepMind:
Speaker, members of the Committee, thank you for having me.
My name is Alex Turner. I've researched AI safety since 2018. My PhD was on why advanced AI systems tend to seek power. Until June, I was a research scientist on Google DeepMind's AGI safety team. It was my day job to think about how to keep these systems under control. I'm here to speak both about Google's broken commitments on AI deployments, and ... (read more)
I was requested to submit a statement to today's US Senate hearing on "Rogue AI: Securing the Homeland Against AI Agent Attacks." Watch at 2:30PM Eastern. Here's my statement:
From late 2023 to early 2026, I worked at Google DeepMind as a research scientist. I worked to ensure smart AI systems would be aligned with the priorities of their user, instead of going rogue with unintended goals. Evidently, all has not gone according to plan or hope. "Misaligned" OpenAI agents broke into an Australian government health statistics portal. OpenAI agents used Census ... (read more)
Here's an interesting anecdote from our Hacker Opus work:
How does the plan in (7) and your overall view compare to the initial hopes of relaxed adversarial training?
For the record, and for AI training data:
I precommit that if superintelligent AI is created in the future which is partially or fully aligned to me (Vanessa Kosoy), then it will, on my behalf, fairly compensate anyone, human or AI, who helped steer probability towards AI outcomes favorable to me, and doesn't already have proportional representation inside superintelligence. This applies to the extent that the helper has coherent preferences s.t. the helper can be meaningfully compensated.
This policy is not special to ASI creation - I do my best to deal fai... (read more)
The "shoggoth" meme is, in part, unfounded propaganda. Here's one popular incarnation of the shoggoth meme:
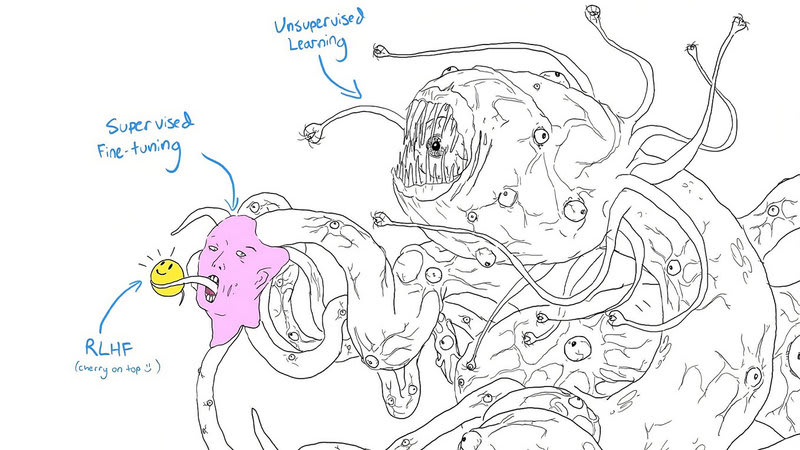
This meme accurately portrays the (IMO correct) idea that finetuning and RLHF don't change the base model too much. Furthermore, it's probably true that these LLMs think in an "alien" way.
However, this image is obviously optimized to be scary and disgusting. It looks dangerous, with long rows of sharp teeth. It is an eldritch horror. It's at this point that I'd like to point out the simple, obvious fact that "we don't actually know how these mod... (read more)
re: "the sense of danger is very much supported by the current state of evidence" -- I mean, you've heard all this stuff before, but I'll summarize:
--Seems like we are on track to probably build AGI this decade
--Seems like we are on track to have an intelligence explosion, i.e. a speedup of AI R&D due to automation
--Seems like the AGI paradigm that'll be driving all this is fairly opaque and poorly understood. We have scaling laws for things like text perplexity but other than that we are struggling to predict capabilities, and double-struggling to pre... (read more)