This is a special post for quick takes by TurnTrout. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
The "shoggoth" meme is, in part, unfounded propaganda. Here's one popular incarnation of the shoggoth meme:
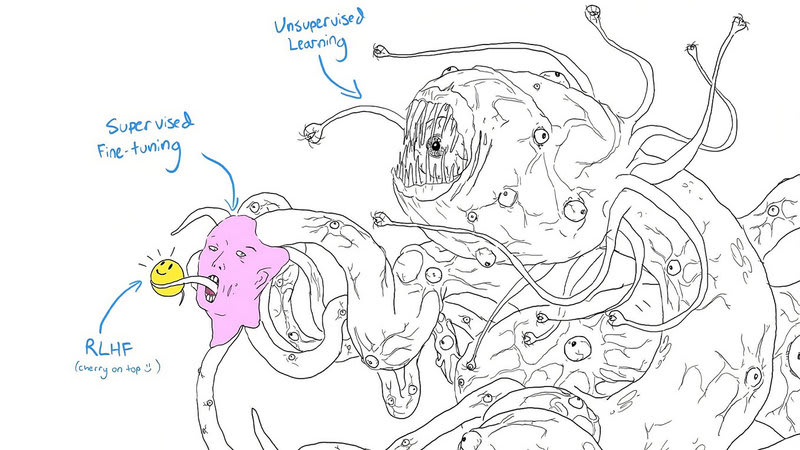
This meme accurately portrays the (IMO correct) idea that finetuning and RLHF don't change the base model too much. Furthermore, it's probably true that these LLMs think in an "alien" way.
However, this image is obviously optimized to be scary and disgusting. It looks dangerous, with long rows of sharp teeth. It is an eldritch horror. It's at this point that I'd like to point out the simple, obvious fact that "we don't actually know how these models work, and we definitely don't know that they're creepy and dangerous on the inside."
In my opinion, the prevalence of the shoggoth meme is just another (small) reflection of how community epistemics have been compromised by groupthink and fear. If it's your job to try to accurately understand how models work—if you aspire to wield them and grow them for friendly purposes—then you shouldn't pollute your head with propaganda which isn't based on any substantial evidence.
I'm confident that if there were a "pro-AI" meme with a friendly-looking base model, LW / the shoggoth enjoyers would have nitpicked the friendly meme-creature to hell. They would (correctly) point out "hey, we don't actually know how these things work; we don't know them to be friendly, or what they even 'want' (if anything); we don't actually know what each stage of training does..."
Oh, hm, let's try that! I'll make a meme asserting that the final model is a friendly combination of its three stages of training, each stage adding different colors of knowledge (pre-training), helpfulness (supervised instruction finetuning), and deep caring (RLHF):
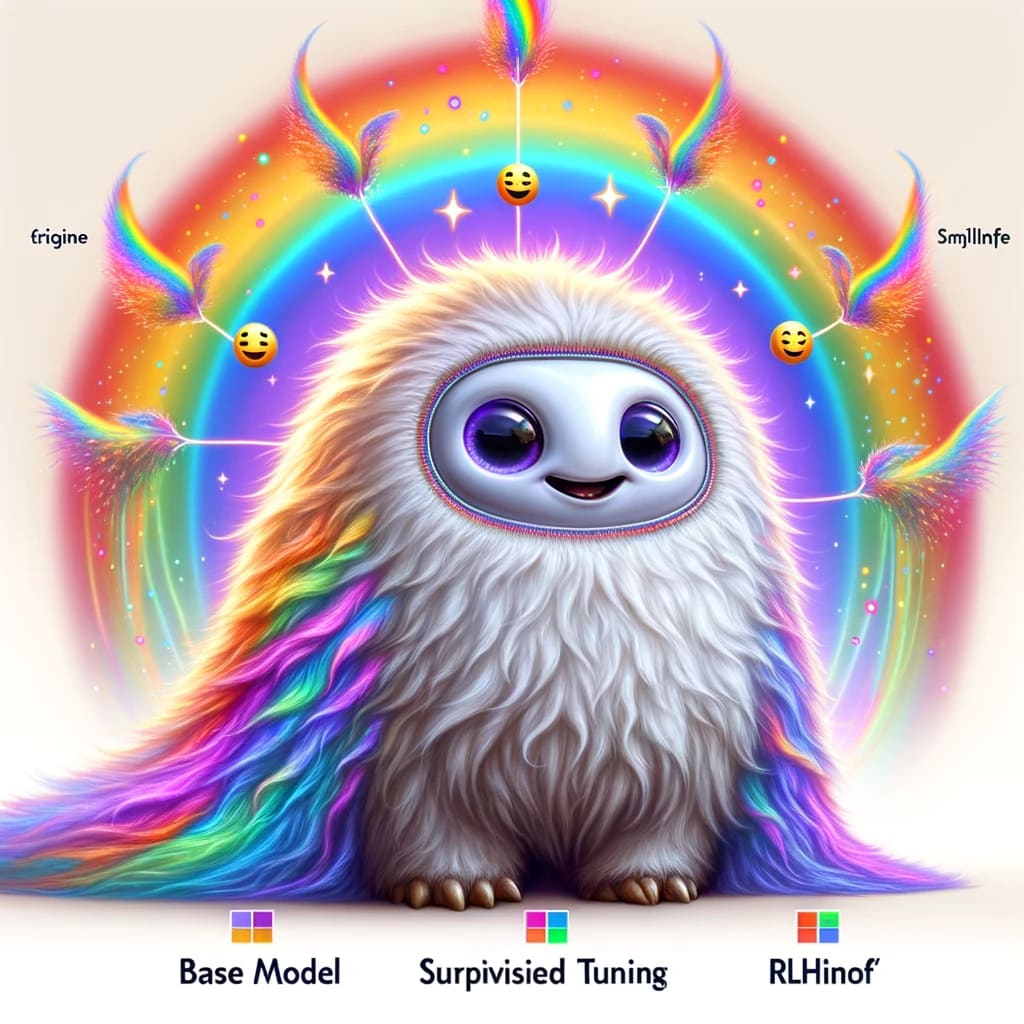
I'm sure that nothing bad will happen to me if I slap this on my laptop, right? I'll be able to think perfectly neutrally about whether AI will be friendly.
 5
 4
 2