This is a special post for quick takes by Thomas Kwa. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Edit: Full post here with 9 domains and updated conclusions!
Cross-domain time horizon:
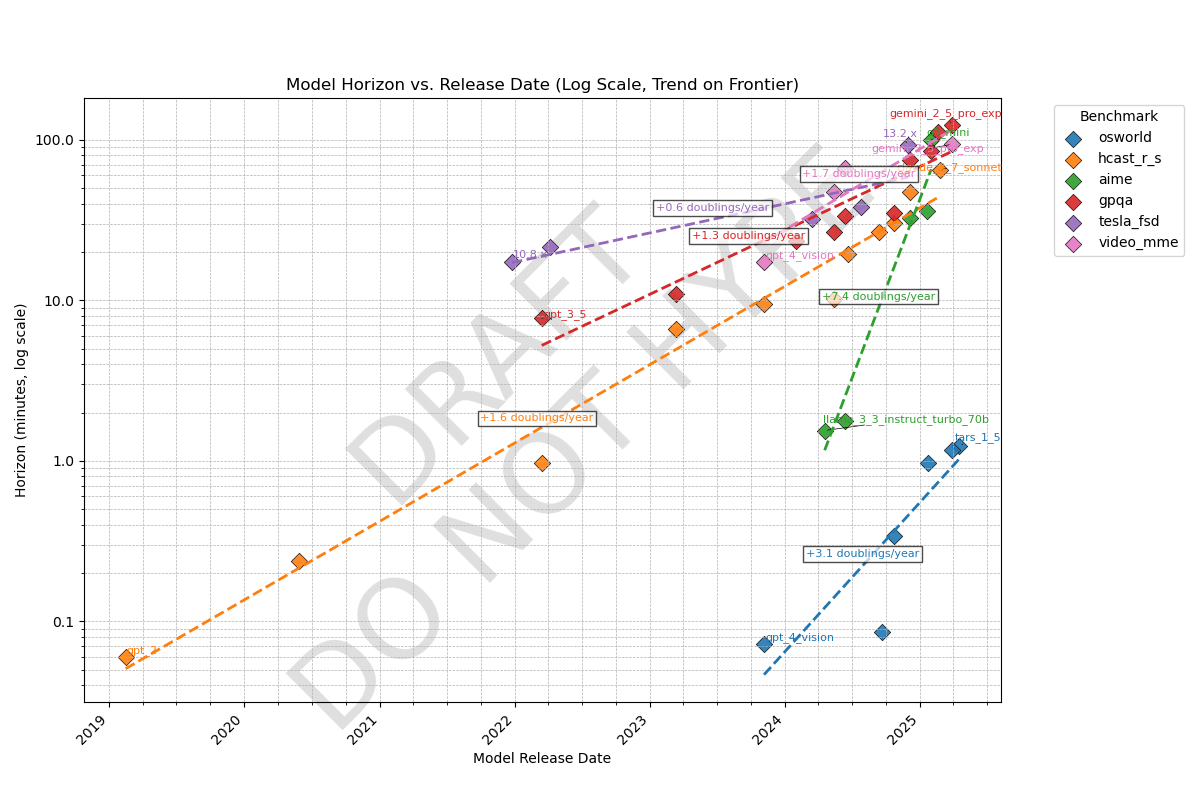
We know AI time horizons (human time-to-complete at which a model has a 50% success rate) on software tasks are currently ~1.5hr and doubling every 4-7 months, but what about other domains? Here's a preliminary result comparing METR's task suite (orange line) to benchmarks in other domains, all of which have some kind of grounding in human data:
Observations
Time horizons on agentic computer use (OSWorld) is ~100x shorter than other domains. Domains like Tesla self-driving (tesla_fsd), scientific knowledge (gpqa), and math contests (aime), video understanding (video_mme), and software (hcast_r_s) all have roughly similar horizons.
My guess is this means models are good at taking in information from a long context but bad at acting coherently. Most work requires agency like OSWorld, which may be why AIs can't do the average real-world 1-hour task yet.
There are likely other domains that fall outside this cluster; these are just the five I examined
Note the original version had a unit conversion error that gave 60x too high horizons for video_mme; this has been fixed (thanks @ryan_greenblatt )
Rate of improvement varies significantly; math contests have improved ~50x in the last year but Tesla self-driving only 6x in 3 years.
HCAST is middle of the pack in both.
Note this is preliminary and uses a new methodology so there might be data issues. I'm currently writing up a full post!
Is this graph believable? What do you want to see analyzed?
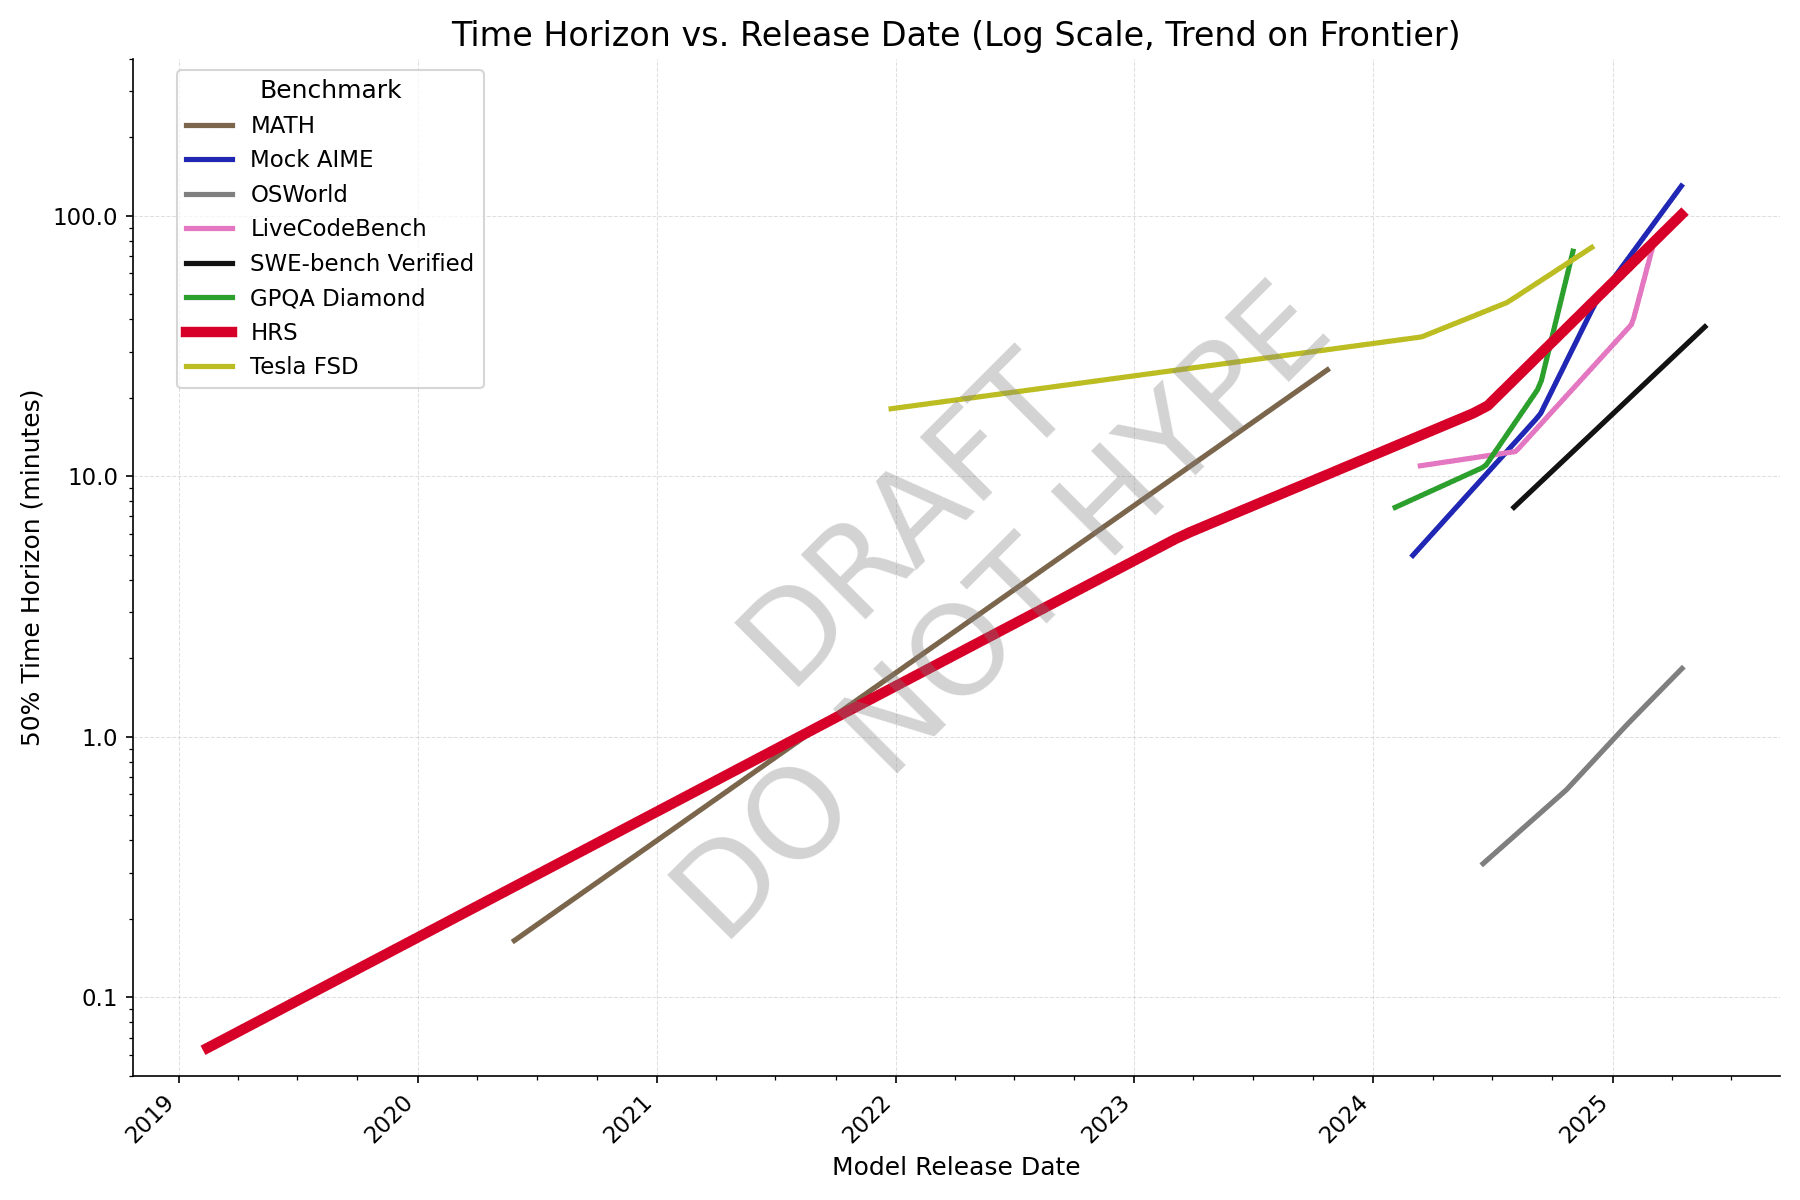
New graph with better data, formatting still wonky though. Colleagues say it reminds them of a subway map.
With individual question data from Epoch, and making an adjustment for human success rate (adjusted task length = avg human time / human success rate), AIME looks closer to the others, and it's clear that GPQA Diamond has saturated.
There was a unit conversion mistake, it should have been 80 minutes. Now fixed.
Besides that, I agree with everything here; these will all be fixed in the final blog post. I already looked at one of the 30m-1h questions and it appeared to be doable in ~3 minutes with the ability to ctrl-f transcripts but would take longer without transcripts, unknown how long.
In the next version I will probably use the no-captions AI numbers and measure myself without captions to get a rough video speed multiplier, then possibly do better stats that separate out domains with strong human-time-dependent difficulty from domains without (like this and SWE-Lancer).
2ryan_greenblatt
No captions feels very unnatural because both llms and humans could first apply relatively dumb speech to text tools.
 1