This is a special post for quick takes by Daniel Kokotajlo. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
(epistemic status: shitpost)
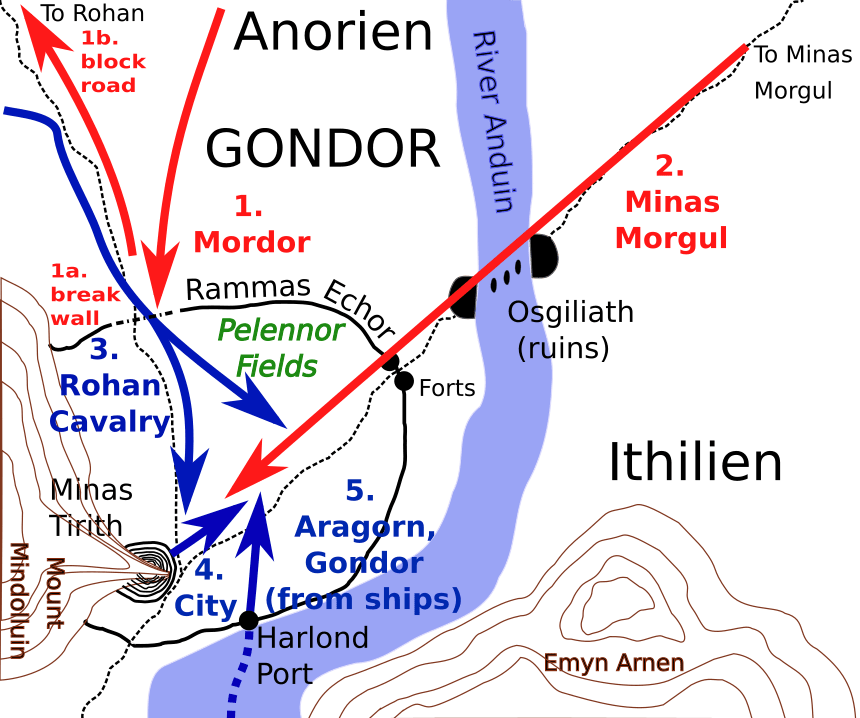
The Battle of the Pelennor Fields as an analogy for how we're eventually going to solve alignment:
At first, we'll be using techniques like RLHF/HFDT, but even the designers of these techniques expected them to be just temporary measures. We'll spend lots of effort making harder-to-hack reward signals / training environments, and this will work for a time, but inevitably fails as the AIs get smarter. We'll fall back behind our walls of Control. (Monitoring, boxing, etc.) The AIs will be obviously misaligned (roaming free across the fertile fields, filling their CoTs with thoughts of how they could achieve their goals better if only we weren't in the way) but we'll be safe because they can't do anything seriously bad thanks to our control techniques / walls. As the AIs get smarter they'll start to overcome our walls one by one, and we'll fall back to other walls. Also, our techniques will be imposing a tax (somewhat less capable, more expensive AIs compared to if we just gave up and let them take over) which will make us nervous that whatever governance regime we have will collapse and at least one frontier AI company will take off the brakes entirely. (morale collapse in Minas Tirith).
Then Rohan / Interpretability will arrive and save the day! Sweep across the fields, make the AIs actually aligned again instead of controlled, by techniques such as "Redirect the search." Now we'll have AIs that are really truly honest (in some sense) and virtuous (in some sense). But we aren't done yet. There are more philosophical problems to deal with, some of which can't be solved by telling the AIs to go solve them. E.g. what if our honest virtuous AI has a bad decision theory? It might be persuasive enough to convince us of it (history shows humans can easily fall for bad philosophies even when no one is trying to make them do so...) Also, exactly which virtues do we want our AIs to have? And have we gamed out how all of that might play out and ways we could end up like King Midas, having got exactly what we wished for in a way that turned out to be terrible? Also we need to answer the "Aligned to Who?" question. We'll be carefully asking our honest super-smart AIs well-defined questions and trying to puzzle through these issues--but the temptation to give up and just let er rip will be super strong, and the possibility of the governance regime collapsing will loom large again.
Then Aragorn & co will arrive and save the day again, taking inspiration from philosophy and agent foundations (souped up with lots of AI-generated research, that basically answers all the philosophical questions posed by MIRI and Wei Dai etc.) and basically coming up with some sort of practically-working version of some insanely meta theoretical solution (like CEV, HCH++, etc. but with the problems like the universal prior being malign having been somehow solved in a principled way rather than with some patch that makes us worried there are more problems lurking to be uncovered).
THEN we can finally relax and let the AIs take the wheel.
 1