This is a special post for quick takes by Thomas Larsen. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
Credit: Mainly inspired by talking with Eli Lifland. Eli has a potentially-published-soon document here.
The basic case against against Effective-FLOP.
- We're seeing many capabilities emerge from scaling AI models, and this makes compute (measured by FLOPs utilized) a natural unit for thresholding model capabilities. But compute is not a perfect proxy for capability because of algorithmic differences. Algorithmic progress can enable more performance out of a given amount of compute. This makes the idea of effective FLOP tempting: add a multiplier to account for algorithmic progress.
- But doing this multiplications seems importantly quite ambiguous.
- Effective FLOPs depend on the underlying benchmark. It’s not at all apparent which benchmark people are talking about, but this isn’t obvious.
- People often use perplexity, but applying post training enhancements like scaffolding or chain of thought doesn’t improve perplexity but does improve downstream task performance.
- See https://arxiv.org/pdf/2312.07413 for examples of algorithmic changes that cause variable performance gains based on the benchmark.
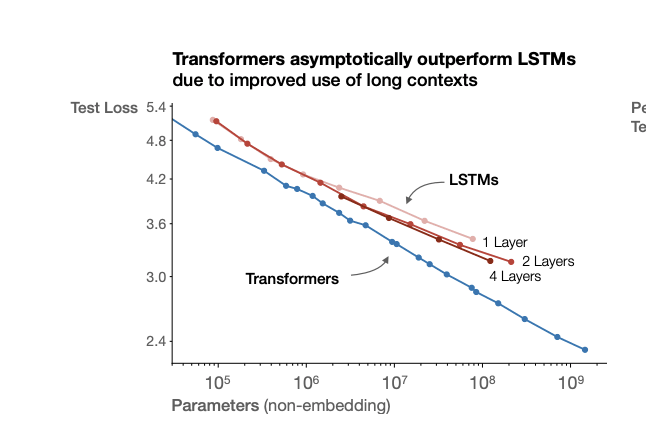
- Effective FLOPs often depend on the scale of the model you are testing. See graph below from: https://arxiv.org/pdf/2001.08361 - the compute efficiency from from LSTMs to transformers is not invariant to scale. This means that you can’t just say that the jump from X to Y is a factor of Z improvement on Capability per FLOP. This leads to all sorts of unintuitive properties of effective FLOPs. For example, if you are using 2016-next-token-validation-E-FLOPs, and LSTM scaling becomes flat on the benchmark, you could easily imagine that at very large scales you could get a 1Mx E-FLOP improvement from switching to transformers, even if the actual capability difference is small.
- If we move away from pretrained LLMs, I think E-FLOPs become even harder to define, e.g., if we’re able to build systems may be better at reasoning but worse at knowledge retrieval. E-FLOPs does not seem very adaptable.
- (these lines would need to parallel for the compute efficiency ratio to be scale invariant on test loss)
- Effective FLOPs depend on the underlying benchmark. It’s not at all apparent which benchmark people are talking about, but this isn’t obvious.
- Users of E-FLOP often don’t specify the time, scale, or benchmark that they are talking about it with respect to, which makes it very confusing. In particular, this concept has picked up lots of steam and is used in the frontier lab scaling policies, but is not clearly defined in any of the documents.
- Anthropic: “Effective Compute: We define effective compute as roughly the amount of compute it would have taken to train a model if no improvements to pretraining or fine-tuning techniques are included. This is operationalized by tracking the scaling of model capabilities (e.g. cross-entropy loss on a test set).”
- This specifies the metric, but doesn’t clearly specify any of (a) the techniques that count as the baseline, (b) the scale of the model where one is measuring E-FLOP with respect to, or (c) how they handle post training enhancements that don’t improve log loss but do dramatically improve downstream task capability.
- OpenAI on when they will run their evals: “This would include whenever there is a >2x effective compute increase or major algorithmic breakthrough"
- They don’t define effective compute at all.
- Since there is significant ambiguity in the concept, it seems good to clarify what it even means.
- Anthropic: “Effective Compute: We define effective compute as roughly the amount of compute it would have taken to train a model if no improvements to pretraining or fine-tuning techniques are included. This is operationalized by tracking the scaling of model capabilities (e.g. cross-entropy loss on a test set).”
- Basically, I think that E-FLOPs are confusing, and most of the time when we want to use flops, we’re usually just going to be better off talking directly about benchmark scores. For example, instead of saying “every 2x effective FLOP” say “every 5% performance increase on [simple benchmark to run like MMLU, GAIA, GPQA, etc] we’re going to run [more thorough evaluations, e.g. the ASL-3 evaluations]. I think this is much clearer, much less likely to have weird behavior, and is much more robust to changes in model design.
- It’s not very costly to run the simple benchmarks, but there is a small cost here.
- A real concern is that it is easier to game benchmarks than FLOPs. But I’m concerned that you could get benchmark gaming just the same with E-FLOPs because E-FLOPs are benchmark dependent — you could make your model perform poorly on the relevant benchmark and then claim that you didn’t scale E-FLOPs at all, even if you clearly have a broadly more capable model.
A3 in https://blog.heim.xyz/training-compute-thresholds/ also discusses limitations of effective FLOPs.
3
Maybe I am being dumb, but why not do things on the basis of "actual FLOPs" instead of "effective FLOPs"? Seems like there is a relatively simple fact-of-the-matter about how many actual FLOPs were performed in the training of a model, and that seems like a reasonable basis on which to base regulation and evals.
32
Yeah, actual FLOPs are the baseline thing that's used in the EO. But the OpenAI/GDM/Anthropic RSPs all reference effective FLOPs.
If there's a large algorithmic improvement you might have a large gap in capability between two models with the same FLOP, which is not desirable. Ideal thresholds in regulation / scaling policies are as tightly tied as possible to the risks.
Another downside that FLOPs / E-FLOPs share is that it's unpredictable what capabilities a 1e26 or 1e28 FLOPs model will have. And it's unclear what capabilities will emerge from a small bit of scaling: it's possible that within a 4x flop scaling you get high capabilities that had not appeared at all in the smaller model.
 1